SEO Optimization

Duplicate Meta Descriptions in WordPress SEO settings

How to Find and Fix Pages with Duplicate Meta Descriptions in WordPress

How to Find and Fix Pages with Duplicate Meta Descriptions in WordPress IL Webdesign | November 15, 2026 | 14 min read SEO OPTIMIZATION Table of Contents 1. What Causes Pages to Have the Same Meta Description? 2. Duplicate Meta Descriptions: Why Do They Matter for SEO? 3. How to Find Duplicate Meta Description Errors 4. How to Check WordPress Meta Descriptions 5. How to Fix Repeated Meta Descriptions in WordPress 6. How Rank Math SEO Settings Can Create Repeated Descriptions 7. How to Write Unique Descriptions for Similar Pages 8. How to Check Whether Your Changes Worked 9. Common Mistakes When Updating Meta Descriptions 10. Frequently Asked Questions 11. Key Takeaways 12. Keep Your Search Descriptions Effective 13. Disclaimer 14. References Have you ever opened your website’s SEO settings and discovered that several pages have exactly the same description? Maybe you copied an older page, used a default template, or never realized your SEO plugin was generating repeated text. Duplicate Meta Descriptions are worth investigating because every important page should communicate what makes its content useful and different. Repeated descriptions do not automatically trigger a Google ranking penalty, but they can make your metadata less informative. While checking your descriptions, it also helps to understand what might prevent Google from properly discovering and indexing your content. These are separate technical concerns, but reviewing both can give you a clearer picture of your website’s search health. In this guide, you’ll learn how to find repeated descriptions, correct them in WordPress, review Rank Math settings, and confirm whether your changes worked. 1. What Causes Pages to Have the Same Meta Description? A meta description is a short summary included in a webpage’s HTML. Search engines can use this information when deciding how to describe a page in search results. Normally, each important page should have a description that reflects its actual content. However, WordPress websites can sometimes generate identical descriptions across multiple URLs. For example, imagine you manage a website with separate pages for website development, content writing, and website maintenance. All three pages might contain this description: Discover our professional digital solutions and learn how we can help improve your online presence. The wording sounds reasonable, but it does not explain what makes each page different. This often happens when someone duplicates an existing page and updates the visible content without changing the SEO description. Other possible causes include default SEO templates, imported pages, automatic descriptions, and custom theme settings. Sometimes an SEO plugin generates descriptions using the same variables across several pages. If those variables return identical information, the resulting descriptions may also match. Before making changes, identify whether the problem comes from individual pages or a shared setting. That distinction can save you considerable time. 2. Duplicate Meta Descriptions: Why Do They Matter for SEO? You might be wondering whether Google penalizes websites for using the same description on several pages. There is no established automatic ranking penalty specifically for repeated meta descriptions. However, descriptions that fail to distinguish pages can make your search listings less informative. According to Google Search Central, Google primarily creates search snippets from page content, although it may use a page’s meta description when that provides a more accurate summary. This means your description is not guaranteed to appear exactly as written. Google may display different text depending on the search query and the information available on the page. Still, a useful, page-specific description gives search engines another relevant summary to consider. Imagine two articles covering different WordPress problems. One explains how to repair broken links. The other teaches readers how to optimize images. If both use the description “Learn useful WordPress tips to improve your website,” neither communicates the article’s specific purpose. A clearer description can help visitors understand what they will find before opening the page. The main goal is to improve clarity and relevance, not to force a particular ranking outcome. 3. How to Find Duplicate Meta Description Errors Before changing anything, you need to identify which URLs share identical descriptions. For a website with only a few pages, you can inspect them manually. Larger websites usually benefit from a crawler that collects metadata across multiple URLs. One option is Screaming Frog SEO Spider, which offers a free version with a crawl limit of 500 URLs. A practical process looks like this: Open Screaming Frog SEO Spider and enter your website URL. Start the crawl and wait for it to finish. Select the Meta Description tab. Filter the results to identify duplicate descriptions. Export the affected URLs or record them in a spreadsheet. Compare the pages to determine whether they should have different descriptions. Prioritize important, indexable pages before making corrections. For example, you might discover that several service pages inherited the same description from a template. You could also find that older articles share generic descriptions because they were created using a copied post. Remember that a crawler can identify matching text, but it cannot automatically determine the best solution for every URL. Some URLs may be redirects, paginated archives, or pages intentionally excluded from indexing. Review those situations before rewriting descriptions unnecessarily. 4. How to Check WordPress Meta Descriptions Once you have a list of affected URLs, open the corresponding pages in your WordPress dashboard. The exact editing process depends on your SEO plugin and WordPress editor. If you use Rank Math, navigate to Pages or Posts and open the content you want to review. Find the Rank Math controls, then open the snippet editor or SEO description field. Compare the description shown there with the text reported by your crawler. You should also check the published page because the description entered in WordPress does not always match the final HTML output. For example, a plugin may generate metadata using a template when no custom description has been entered. Caching can also temporarily cause an older version of the page to remain visible. To inspect the published description, open the webpage in your browser and select View
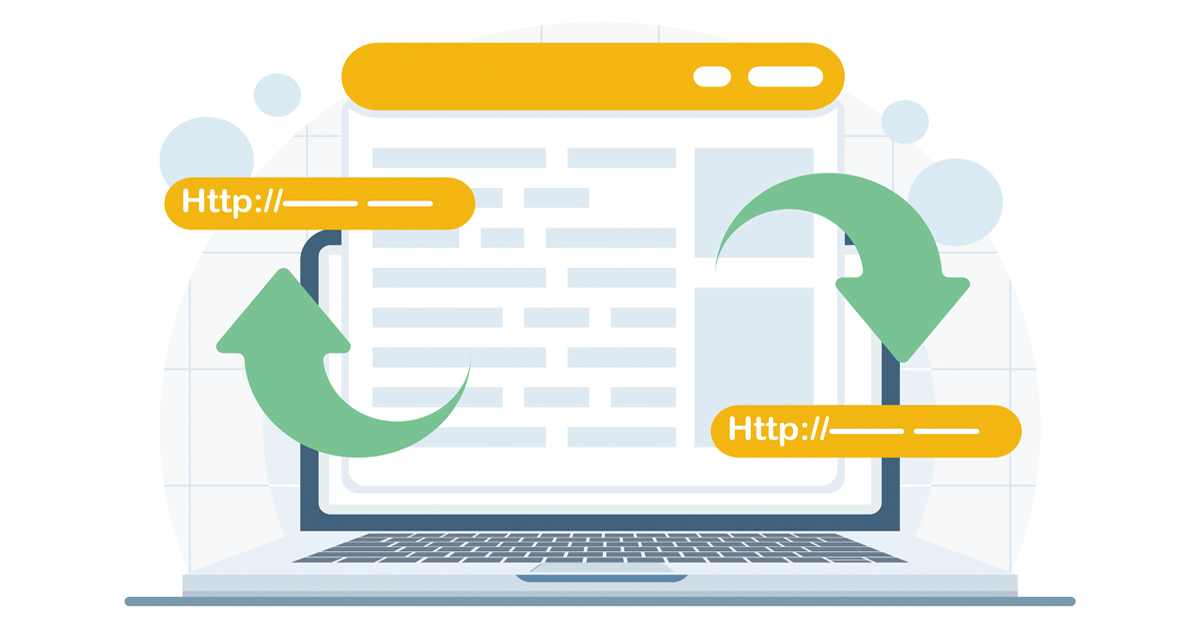
Redirect chains illustrated through a WordPress URL path leading to the final page

How to Find and Fix Redirect Chains in WordPress Using Free Tools

How to Find and Fix Redirect Chains in WordPress Using Free Tools IL Webdesign | November 8, 2026 | 13 min read SEO OPTIMIZATION Table of Contents 1. Understanding What Happens When a URL Redirects More Than Once 2. Redirect Chains: Why Do They Happen? 3. Why Multiple Redirects Can Affect Website Performance 4. How to Check Redirects Using Free Tools 5. How to Find WordPress Redirect Chains 6. How to Fix Redirect Chains Step by Step 7. How to Review WordPress Redirect Settings 8. How to Test Redirects After Making Changes 9. Common Redirect Mistakes to Avoid 10. Frequently Asked Questions 11. Key Takeaways 12. Keep Your Redirects Working 13. Disclaimer 14. References Have you ever changed a page URL, updated your website, or installed a redirect plugin, only to discover that visitors are being sent through several addresses before reaching the right page? These extra steps are known as redirect chains, and they can develop quietly as your website grows. You might not notice anything unusual because the final page still loads. However, unnecessary redirects can add delays, complicate website maintenance, and make technical problems harder to identify. If you’re already investigating what can affect your website’s loading performance, checking your redirect paths is another useful step. In this guide, you’ll learn how to identify unnecessary redirects using free tools, understand what’s causing them, make safer changes in WordPress, and confirm that your fixes work correctly. 1. Understanding What Happens When a URL Redirects More Than Once A redirect tells your browser to visit a different URL instead of the one originally requested. This is useful when you rename a page, move content, or reorganize your website. Rather than leaving visitors with an outdated address, a redirect sends them to the appropriate destination. For example, imagine you originally published an article at: example.com/old-guide Later, you change its address to: example.com/new-guide A redirect allows someone using the original address to reach the updated article. Now imagine you change the URL again: example.com/updated-guide If you don’t update the original redirect, visitors might follow this path: /old-guide → /new-guide → /updated-guide The browser must process two redirects before reaching the final page. A more direct arrangement would be: /old-guide → /updated-guide The difference might seem small, but unnecessary steps can accumulate as your website changes. The important thing to understand is that redirects themselves are not bad. They help preserve access to moved content. The problem is keeping unnecessary intermediate destinations when a more direct route is available. 2. Redirect Chains: Why Do They Happen? Most redirect problems develop gradually rather than appearing because of one obvious mistake. You might rename a page today, reorganize your content next month, and change your permalink structure later. Each update can introduce another redirect rule. If older rules remain unchanged, visitors may continue passing through outdated URLs. Several situations can contribute to this problem. For example, switching from HTTP to HTTPS may introduce one redirect. Changing from a www address to a non-www address may introduce another. WordPress plugins can also create redirects when pages move. Meanwhile, your hosting provider or server configuration might manage separate rules. None of these settings is necessarily incorrect on its own. Problems appear when they overlap or send visitors through more addresses than necessary. Consider a website that originally used: example.com/blog/old-article Later, the article moves to: example.com/resources/article Eventually, you simplify the address to: example.com/article If the original URL still points to the intermediate address, visitors must follow both redirects. This is why reviewing older rules matters whenever you make structural changes. You want each outdated URL to reach its intended destination without unnecessary detours. 3. Why Multiple Redirects Can Affect Website Performance Every additional redirect requires the browser to process another response and request another URL. Depending on the server, network connection, and number of redirects, those extra requests can increase the time needed to reach the final page. You might barely notice one additional redirect on a fast connection. However, several unnecessary steps can become more noticeable when network conditions are slower. Redirects can also complicate website crawling. Search engines need to follow URL changes to understand where content has moved. Although they can process redirects, unnecessarily complicated paths make your website harder to maintain and troubleshoot. According to Google Search Central, Googlebot follows redirects within documented limits, and directing requests toward the final destination is generally preferable to maintaining unnecessarily long sequences. This doesn’t mean every redirect causes an indexing problem or reduces your search rankings. A redirect may be completely appropriate when a page has permanently moved. The concern is whether your configuration creates avoidable steps. For example, if an old article URL passes through three outdated addresses before reaching the current article, reviewing those rules may help simplify the path. Think of redirect cleanup as part of routine website maintenance rather than a guaranteed ranking improvement. A shorter, correctly configured redirect path is generally easier to test, understand, and maintain. 4. How to Check Redirects Using Free Tools You don’t need an expensive subscription to investigate how your URLs behave. Several free methods can show whether a URL redirects and where it eventually leads. Using an online redirect chain checker An online redirect checker can display the sequence of addresses involved in a request. You enter the original URL, run the test, and review the results. Depending on the tool, you may see the intermediate addresses, HTTP status codes, and final response. For example: URL A (301) → URL B (301) → URL C (200) Here, the first two responses indicate redirects. The final 200 response generally means the requested destination was successfully retrieved. If your original URL could point directly to URL C, the intermediate redirect may be unnecessary. Remember that online tools vary in accuracy and functionality. Avoid submitting private staging URLs, sensitive query parameters, or other confidential information to unfamiliar services. Using browser developer tools Your browser can also help you inspect redirect behavior. In Google Chrome, open Developer Tools,
Website page speed performance analysis on a computer

Why Is My Website So Slow and How Can I Speed It Up?

Why Is My Website So Slow and How Can I Speed It Up? IL Webdesign | October 7, 2026 | 10 min read SEO OPTIMIZATION Table of Contents 1. Understanding What Makes a Website Feel Slow 2. Website Page Speed: What Should You Actually Measure? 3. Why Images Can Make Pages Load Slowly 4. How JavaScript and CSS Affect Loading Performance 5. How Hosting and Server Response Time Affect Site Speed 6. Website Speed Optimization: Where Should You Start? 7. How Caching and Content Delivery Can Improve Performance 8. How Core Web Vitals Help You Evaluate Page Performance 9. Common Mistakes That Can Keep a Website Slow 10. Frequently Asked Questions 11. Key Takeaways 12. Improve Your Website Performance 13. Disclaimer 14. References A website can look polished and still feel frustratingly slow. You click a page, wait for the main content to appear, try to interact with something, and wonder why everything seems to take longer than it should. Improving website page speed starts with understanding what is creating the delay. Sometimes the problem is a large image. Other times, scripts, fonts, hosting, caching, or several smaller issues are working together. Before changing individual settings, it helps to understand which performance signals can reveal problems with the visitor experience. This gives you a better starting point than randomly installing optimization plugins or deleting files. In this guide, you will learn what can make a website slow, how to measure performance, which improvements are worth prioritizing, and how to avoid common optimization mistakes. 1. Understanding What Makes a Website Feel Slow When people describe a slow website, they are not always talking about the same problem. One page might take several seconds before anything useful appears. Another may display quickly but remain difficult to interact with because the browser is still processing scripts. A third may seem ready, only for text, buttons, or images to suddenly shift position. All three situations can create a poor experience. This is why site speed should not be reduced to a single number. Your website is loading many different resources, and each one can influence how quickly visitors see and interact with the page. For example, imagine a service page containing a large hero image, several custom fonts, an embedded video, analytics scripts, a chat widget, and multiple plugins. None of those elements automatically creates a performance problem. Together, however, they can increase the amount of work the browser has to complete. The useful question is not simply whether your site is slow. You need to determine what is causing the delay and what visitors are actually experiencing. That distinction can save you from making unnecessary changes. 2. Website Page Speed: What Should You Actually Measure? A speed test can produce a lot of information. The challenge is knowing which measurements deserve your attention. A useful starting point is Google’s PageSpeed Insights, which can help you evaluate performance and identify potential opportunities for improvement. You may see information about loading, responsiveness, visual stability, images, scripts, and other resources. But do not treat a performance score as the entire story. A page may behave differently depending on the visitor’s device, network connection, browser, geographic distance from the server, and whether certain resources are already cached. That is also why Google’s guidance for learning about web performance looks at performance as a broader discipline rather than a single score. When reviewing results, focus on patterns. If large images repeatedly appear as a problem, investigate your images. If scripts are creating substantial processing work, examine where those scripts come from and whether you need all of them. Measurement should help you decide what to investigate next. It should not become a contest to chase a perfect score. 3. Why Images Can Make Pages Load Slowly Images are one of the first places worth checking when a visually rich page loads slowly. Modern websites often use large hero photographs, service images, galleries, team photos, background graphics, and blog images. Uploading those files directly from a camera or design program can leave you with much more image data than the page actually needs. Suppose your content area displays an image at roughly 800 pixels wide, but you upload a photograph several thousand pixels wide. Visitors may end up downloading a much larger file than necessary. Image optimization can involve choosing suitable dimensions, compressing files appropriately, using efficient formats when supported, and avoiding unnecessary image resources. Lazy loading can also be useful in the right situation. Images farther down a page may not need to load immediately when someone first arrives. The goal is not to make every image as tiny as technically possible. Excessive compression can noticeably damage visual quality. Instead, balance quality with the amount of data visitors actually need to download. If your pages contain many large visual assets, image review is often one of the most practical places to begin. 4. How JavaScript and CSS Affect Loading Performance Images are easy to notice because you can see them. JavaScript and CSS can be less obvious, but they can also influence page performance. CSS tells the browser how elements should look and behave visually. JavaScript can power menus, sliders, calculators, pop-ups, analytics, animations, forms, tracking tools, and many other interactive features. The problem is not simply that a website uses JavaScript or CSS. Modern websites depend on both. Problems can appear when a page loads more code than it needs, loads resources inefficiently, or requires the browser to perform a large amount of work before the visitor can interact comfortably. Third-party scripts deserve particular attention. A website may gradually collect analytics platforms, advertising scripts, chat tools, heatmaps, social widgets, and other integrations. Each tool may have a legitimate purpose, but the cumulative effect matters. When you are investigating broader performance concerns, reviewing the technical health of your website as a whole can help you avoid treating one symptom as though it exists in isolation. Before removing code, determine what it does and whether another part of
Website indexing issues shown through a Google indexing and technical SEO review

Why Isn’t Google Indexing My Website and How Can I Fix It?

Why Isn’t Google Indexing My Website and How Can I Fix It? IL Webdesign | October 4, 2026 | 10 min read SEO OPTIMIZATION Table of Contents 1. Understanding How Google Finds and Indexes Pages 2. Website Indexing Issues: Why Pages May Be Missing From Google 3. Check Whether Google Can Discover the Page 4. Review Robots.txt and Crawl Access 5. Look for a Noindex Tag That May Be Blocking the Page 6. Check Canonical Tags and Duplicate URLs 7. Make Sure Your XML Sitemap Is Helping Google Find Important Pages 8. Use Google Search Console Indexing Tools to Diagnose the Problem 9. How to Fix Common Google Indexing Issues Step by Step 10. Frequently Asked Questions 11. Key Takeaways 12. Build a Healthier Foundation for Search 13. Disclaimer 14. References You publish an important page, wait for it to appear in search, and then discover that Google still does not seem to know it exists. Website indexing issues can be frustrating because the page may look completely normal when you visit it yourself. The problem is often somewhere beneath the visible page. Google first needs to discover the URL, access it, understand what it contains, and decide whether that version belongs in its index. If you are troubleshooting more than one technical problem, learning how to evaluate structured data as part of your wider SEO setup can also help you understand why individual optimizations work best when the underlying page is technically accessible. Here is how to investigate indexing problems methodically instead of making random changes and hoping Google notices. 1. Understanding How Google Finds and Indexes Pages Before you start fixing anything, it helps to understand that crawling and indexing are not the same thing. Google first needs to discover a URL. It may find the page through an internal link, an XML sitemap, or another source. Google can then crawl the URL and process what it finds. Indexing happens when Google processes a page and adds it to its search index, where it may become eligible to appear in search results. A page being live on your website does not automatically mean it has completed that process. This distinction matters because different problems happen at different stages. If Google cannot discover the URL, changing the page’s copy probably will not solve the problem. If Google discovers the page but encounters an indexing directive, improving internal links alone may not fix it either. The first goal is to determine where the process is breaking down. 2. Website Indexing Issues: Why Pages May Be Missing From Google There is rarely one universal explanation for a missing page. Sometimes the problem is simple. A newly published page has not been discovered yet. Other times, Google knows about the URL but does not index it because of a technical instruction or because another URL is treated as the preferred version. Google’s Page Indexing Report documentation explains that URLs can remain unindexed for legitimate reasons, including robots.txt rules, a noindex directive, duplicate URLs, and removed pages returning a 404 response. Google also notes that you should not expect every URL on a website to be indexed. That last point is important. Your goal is not necessarily to make the indexed-page count equal the total number of URLs your website can generate. Filter pages, duplicate variations, obsolete URLs, and other low-value versions may not belong in the index. Focus first on pages that are important to visitors and search visibility. 3. Check Whether Google Can Discover the Page Imagine publishing a useful article but never adding a link to it from anywhere else on your website. You know the URL because you created it. Google may have a much harder time finding it. Internal links create pathways between pages. A clear site structure helps both visitors and search engines move from established pages to newer or deeper content. Start by checking whether the missing page can be reached naturally from another relevant page on your website. Avoid creating links simply for search engines. The connection should make sense to a person following it too. For example, an article about fixing an indexing problem could naturally link from a broader technical SEO guide. A service page might link to supporting educational resources that help visitors understand the subject in more detail. If an important page is isolated from the rest of your site, improving its internal connections gives search engines another way to discover it. This is also why site architecture deserves attention as your website grows. New content should become part of the website, not sit on an island. 4. Review Robots.txt and Crawl Access Your robots.txt file provides instructions about crawling parts of your website. A mistake here can prevent Googlebot from crawling URLs you actually want search engines to access. Do not assume that every robots.txt restriction is an error. Some sections of a website may be intentionally restricted from crawling. The problem occurs when an important public page falls under a rule that was meant for something else. For example, a website may have received temporary crawling restrictions during development. If those rules remain after launch, important sections can become difficult for search engines to access. Check the actual path of the affected URL against your robots.txt directives. You should also look beyond robots.txt. A page may require authentication, return an unexpected HTTP response, redirect somewhere else, or experience a server problem when a crawler tries to access it. A page that works for you in a browser is not proof that Google can access it under the same conditions. 5. Look for a Noindex Tag That May Be Blocking the Page A noindex directive tells compatible search engines not to include a page in their search index. That can be useful. You might intentionally keep certain utility pages or other URLs out of search. Problems begin when the directive appears on a page that you actually want indexed. This can happen after a website redesign, staging-to-production migration, plugin
schema markup implementation for structured data

How Do You Add Structured Data to Your Website Correctly?

How Do You Add Structured Data to Your Website Correctly? IL Webdesign | September 6, 2026 | 12 min read SEO OPTIMIZATION Table of Contents 1. Understanding What Structured Data Actually Does 2. Schema Markup: Where Should You Start? 3. Choose a Structured Data Type That Fits the Page 4. Decide Which Properties Actually Belong 5. Add Structured Data Markup Without Creating Conflicts 6. Test Your Structured Data Before Relying on It 7. Understand and Fix Common Structured Data Errors 8. Review Your Markup After Website Changes 9. Common Implementation Mistakes to Avoid 10. Frequently Asked Questions 11. Key Takeaways 12. Build a Healthier Search Foundation 13. Disclaimer 14. References Adding structured data can sound complicated when you first encounter terms such as JSON-LD, properties, validation, and rich results. In practice, schema markup becomes much easier to understand once you focus on what the code is actually supposed to describe. The goal is not to add as much code as possible. You want to give search engines accurate information about content that already exists on your page. Before you start, it is worth checking your website for technical issues that could affect how search engines access your pages. Once you know the technical foundation is in good shape, you can focus on choosing the right structured information, implementing it carefully, and testing the result. This guide walks you through that process in a practical order. 1. Understanding What Structured Data Actually Does When you look at a webpage, you can usually recognize what its different pieces mean without thinking about it. You know that a large heading may be an article title. You can recognize an author’s name, publication date, product details, business information, or event date from the way the page is written and designed. Search engines process those pages differently. Structured data gives them additional machine-readable information about what particular content represents. Instead of relying entirely on surrounding text and page structure, a search engine can use this information as another source of context. For example, imagine an article that displays a headline, author, featured image, and publication date. A reader can recognize those elements visually. Structured information can identify those relationships in a standardized format. That does not mean the code replaces your visible content. Your actual page remains the foundation. The structured information should accurately describe what is already there. Think of structured data as a way of labeling information clearly for machines, rather than adding something completely separate for visitors. 2. Schema Markup: Where Should You Start? Start with the page, not the code. Before choosing a type or opening a plugin, ask yourself one simple question: What does this page primarily represent? Maybe it is an article. Perhaps it describes a product, person, organization, event, recipe, or another identifiable entity. Once you know the answer, you have a much better starting point. This is important because one of the easiest mistakes is assuming that adding more types will automatically improve SEO. It will not. If you add information that does not accurately represent the page, you can make the implementation more confusing rather than more useful. A sensible process is to identify the page’s purpose, review its visible information, check what your website already generates, select an appropriate type, choose relevant properties, implement the code, and then test it. You do not need to tackle every possible option at once. Start with the clearest description of the page and build from there. 3. Choose a Structured Data Type That Fits the Page Once you understand what the page represents, you can look for a suitable structured data type. Types provide a way to identify what an entity or piece of content represents. Different pages naturally call for different descriptions. An article and a product page, for example, do not serve the same purpose. Their structured information should reflect that difference. The official Schema.org documentation provides the vocabulary, type hierarchy, data model, and related developer resources you can use when exploring the available options. You may encounter types associated with articles, organizations, people, products, events, recipes, videos, local businesses, and many other entities. That does not mean your website needs all of them. Suppose you publish an educational article. Choosing a type that accurately describes an article makes sense. Choosing an unrelated type because you like the way another search result looks does not. There is another distinction worth understanding. Schema.org provides a broad vocabulary. Google maintains separate documentation explaining which structured data features it supports in Google Search and what requirements apply to them. A type can exist in the broader vocabulary without automatically producing a special Google search appearance. Choose what accurately describes your page first. Then check the requirements of any search feature you are specifically interested in. 4. Decide Which Properties Actually Belong After choosing a type, you can decide which schema properties accurately describe the entity. Properties add details. For an article, those details could include information associated with its headline, author, image, or publication date. Other types have properties that make sense for the information they describe. The important part is accuracy. Do not fill properties simply because they are available. If a value is incorrect, outdated, or unrelated to the visible page, including it does not make the implementation stronger. Imagine that a website template automatically includes an old image URL. The code may still be formatted correctly, but the information no longer reflects the current page. The same problem can happen with names, dates, URLs, descriptions, and other values. When reviewing properties, ask whether the information is visible or appropriately represented on the page, whether it is current, and whether it accurately describes the entity. This is one reason you should review generated information rather than assuming a plugin has handled everything perfectly. Automation can save time, but accuracy still needs human review. 5. Add Structured Data Markup Without Creating Conflicts After deciding what you want to describe, you need a way to add that information
Title tags for SEO displayed in website search results

How to Write Better Title Tags for Your Website

How to Write Better Title Tags for Your Website IL Webdesign | September 3, 2026 | 12 min read SEO OPTIMIZATION Table of Contents 1. Understanding What a Title Tag Actually Does 2. Title Tags for SEO: What Makes a Good One? 3. Start With the Purpose of the Page 4. How to Write Title Tags That Make Sense to People 5. How Long Should a Website Title Be? 6. Use Keywords Without Making the Title Sound Forced 7. Keep Website Title Tags Unique 8. Why Google May Show a Different Title 9. Common Title Tag Mistakes to Avoid 10. Frequently Asked Questions 11. Key Takeaways 12. Build a Stronger Foundation for Search 13. Disclaimer 14. References Writing title tags for SEO sounds straightforward. You describe the page, include the main topic, and move on. In practice, it is easy to end up with titles that are vague, repetitive, overloaded with keywords, or disconnected from what people actually find on the page. A good title gives both people and search engines useful context. It should communicate the page’s purpose quickly without trying to squeeze every possible search phrase into a single line. If you are reviewing more than your page titles, it may help to look for other technical issues across your website before making isolated changes. A title can be well written while the page itself still has problems involving indexing, redirects, crawl access, or other technical elements. In this guide, you will learn how page titles work, what makes them useful, how to write them naturally, and which common mistakes are worth fixing. 1. Understanding What a Title Tag Actually Does A title tag is the text inside the HTML <title> element of a web page. It gives search engines and other systems information about the subject of that particular document. For example, the HTML might look like this: <title>How to Care for Indoor Plants During Winter</title> You will often hear people use terms such as page title, SEO title, and title tag to describe roughly the same part of a webpage. There is one distinction worth understanding, however. The title you place in the HTML is not necessarily the exact title someone will see in Google Search. Google calls the clickable heading that appears for a result a title link. The HTML title element can influence that title link, but Google can consider other information from the page as well. This is why writing a useful title is about more than filling in an SEO field in your content management system. You are creating a concise description of what the page actually offers. 2. Title Tags for SEO: What Makes a Good One? A useful title should answer a simple question for the person scanning search results: What will I find if I open this page? If someone cannot tell, the title may be too broad. Imagine you are searching for instructions on cleaning a leather sofa. You see these two titles: Cleaning Tips and Advice and How to Clean a Leather Sofa Without Damaging It The second gives you much more information. You know what the page covers before you click. That clarity is important. According to Google Search Central, Google recommends creating descriptive and concise text for <title> elements. Google also advises against vague wording, keyword stuffing, and repeated boilerplate text. That does not mean there is one perfect formula for every page. A product page, service page, educational article, category page, and homepage all serve different purposes. Their titles should reflect those differences. The goal is to make the subject clear without making the wording sound mechanical. 3. Start With the Purpose of the Page Before you write a title, forget about character counts and keywords for a moment. Ask yourself: What is this page actually supposed to help someone do or understand? Your answer gives you a starting point. Suppose you have an article explaining how homeowners can identify a leaking roof. The page may discuss ceiling stains, damaged shingles, moisture in the attic, and several other warning signs. You could try to fit all of those details into the title, but that would make it unnecessarily complicated. A clearer title could simply be: How to Tell If Your Roof Is Leaking The details belong in the article. The title’s job is to summarize the central purpose. This approach also helps prevent a common problem where the title targets one idea but the content focuses on something else. If a title promises a comparison, the page should actually compare the options. If it promises seven steps, readers should find seven steps. If it says the page is for beginners, the content should not assume advanced knowledge. Your page title and your actual content should make the same promise. 4. How to Write Title Tags That Make Sense to People When you are learning how to write title tags, it is tempting to start with a template. Templates can save time, but they can also make every page sound nearly identical. A better method is to write for clarity first. Start by describing the page in one sentence. Then shorten that sentence until it works as a title without losing its meaning. For example, you might begin with: This page explains how someone can prepare their garden before the first winter freeze. That could become: How to Prepare Your Garden for the First Winter Freeze Now read the title as though you were seeing the website for the first time. Would you understand it without seeing the rest of the page? Next, write two or three alternatives. Your first version is not always your strongest one. You might compare: Winter Garden Preparation Tips How to Prepare Your Garden for Winter 7 Ways to Prepare Your Garden Before the First Freeze Each version creates a slightly different expectation. The right choice depends on what the page actually contains. Once you have a few options, remove words that do not add useful information. You are
Call Us917-239-5386 Free Consultation